I’m unusually excited to write this piece because, for a long time, data quality was hard to teach the right way.
We had to spend so much time on the mechanics: how to impute missing values, how to remove duplicates, how to standardize messy fields, how to get a dataset into a shape that tools would even accept.
Those skills still matter, but they used to consume the entire lesson, and thanks to LLMs and AI agents - they don't anymore.
We rarely had enough room to teach the more important part: how to recognize what kind of failure you are actually looking at, and how that failure distorts a business decision.
Now that AI can increasingly help with the mechanics, we finally get to focus on the thinking. And completeness is the right place to start, because some of the most dangerous data problems do not look broken at all.
Your Dashboard Isn't Wrong. It's Missing Half the Story.
This is a tale as old as time - Traffic looked stable. Orders looked soft. The dashboard was neat, current, and persuasive enough to trigger a meeting about landing pages, ad quality, and whether iPhone users had suddenly become harder to convert.
Then someone checked the tracking release - Marketing thought mobile conversion had collapsed.
An iOS change had quietly stopped session events from being recorded. Orders were still coming through. Sessions were not. Nothing in the chart looked obviously broken. The numbers were real. The conclusion was fiction.
That is completeness.
I know this - df.fillna(), right?
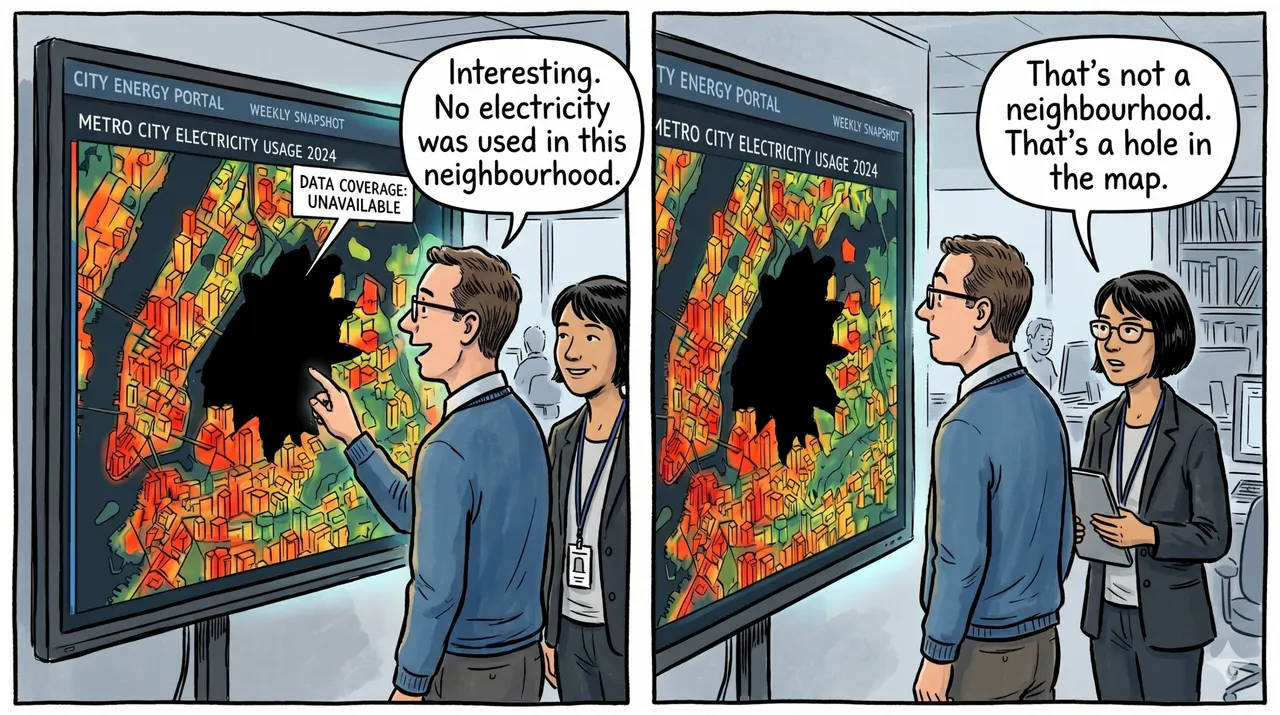
Completeness is not just "do we have nulls?" It is whether the data required to answer the question actually exists. A dataset can look tidy and still be missing the exact slice of reality your decision depends on.
This is what makes completeness dangerous in the LLM era.
An AI assistant can help you fill missing fields, write profiling queries, and flag suspicious gaps. What it cannot do for you is decide whether the dataset in front of you is sufficient for the decision you are making.
That part is still judgment.
The most dangerous missing value is the one you do not know is missing
As analysts, we are trained to notice blanks.
We are less trained to notice absent coverage.
If a column is full of `NULL`s, at least the problem announces itself.
If an entire platform, country, channel, or event type silently disappears, the result can still look perfectly plausible.
If our DEs wrote "" into the cell, because the schema says "null=False" - how would you know?
A time series does not scream when it becomes partial.
This is why completeness failures often produce the most confident mistakes. The dashboard still has lines on it. The KPI still has two decimal places. The meeting still happens on time. Missingness hides inside normality.
"No data" versus "zero"
Businesses constantly confuse absence with inactivity.
Zero orders means nobody bought.
No order records means you do not know whether anyone bought.
Zero sessions from iOS means nobody visited.
Missing iOS events means you don't know how many visited.
Those are not subtle distinctions. They are different worlds.
This is the heart of missingness, yet many dashboards flatten them into the same visual outcome: a low number.
This matters because people respond differently to zero than to uncertainty.
Zero encourages action. Uncertainty should encourage inspection.
When the dashboard cannot distinguish between them, teams rush into explanations for behavior that may never have happened.
Not all missingness born the same
Once you notice data is missing, the next question is not just how much is missing. It is why.
Statisticians usually split missingness into three broad types:
- `MCAR` (Missing Completely At Random): the missing values have no meaningful relationship to the observed data or the missing value itself
- `MAR` (Missing At Random): the missingness is related to other observed variables, even if not to the missing value directly
- `MNAR` (Missing Not At Random): the missingness is related to the missing value itself, or to the underlying condition being measured
These labels sound academic until you realize they imply very different risks.
MCAR - Missing Completely At Random
If data is MCAR, the missing rows are annoying but less likely to systematically bias the result. If it is MAR, you may be able to model or adjust for the pattern using variables you still observe. If it is MNAR, the missingness is itself part of the story, which means simple fixes can make the analysis look cleaner while pushing it further from the truth.
This is one of the fastest ways analysts fool themselves. They see missing values, apply one generic treatment, and move on as if every absence were created equal.
Example 1: Healthcare and MCAR
A hospital lab system loses a small batch of blood test results because one device goes offline for twenty minutes during routine maintenance. The affected patients were not selected for any clinical reason. Their missing test values are mostly the result of operational bad luck.
That is close to MCAR.
The data is still incomplete, but the missingness is less likely to be systematically tied to patient severity, age, diagnosis, or the test result itself. You still need to handle it carefully. But the risk is not just missing values. The risk is assuming every missing healthcare record reflects patient behavior when sometimes it just reflects hardware behaving badly.
Example 2: Education and MAR
A school district is analyzing assignment completion. It finds that homework submission status is missing more often for students in classes where teachers adopted a new learning platform late.
That is closer to MAR.
The missingness is not random, but it is related to an observed variable: class or teacher platform adoption. If you know which classrooms switched late, you can at least reason about the bias and potentially adjust for it. Without that context, you might tell a story about student disengagement when the real problem was uneven system rollout.
Example 3: Consumer finance and MNAR
A lender asks applicants to self-report income during a pre-qualification flow. Missing income values cluster among applicants with more variable or lower earnings, who are more likely to skip the question rather than disclose an uncomfortable answer.
That is classic MNAR territory.
The missingness is not just attached to the application record. It is tied to the unobserved value itself. People with certain income characteristics are more likely not to report income at all. If you replace those blanks with a generic median and continue as if the sample stayed representative, you have not solved the problem. You have disguised it.
The practical lesson is simple: before fixing missing data, decide what kind of missingness you are dealing with. Otherwise you risk treating a biased absence as a harmless gap.
Completeness depends on the question, not the table
The same dataset can be complete for one purpose and incomplete for another.
If you want total completed orders yesterday, a table of purchases may be enough. If you want conversion rate by device, you also need reliable session data by device. If you want CAC by channel, you need attributable spend, sessions, conversions, and consistent campaign metadata.
Completeness is not a property you award to a table once and move on. It is conditional.
Complete for what?
Across which time range? For which entities? At what grain?
This is where your "clean" dataset can fail. They are complete enough to exist in production, but not complete enough to answer the business question currently being asked.
How you might miss it
You start with the metric instead of the coverage, and ask:
- What is conversion this week?
- Which channel dropped?
- Is mobile underperforming?
Instead - before you start the analysis, ask -
- Do we have coverage for all relevant dates?
- Do all platforms still emit the events we need?
- Did a release, migration, or vendor change alter what is captured?
- Are some countries, channels, or customer segments missing entirely or is everything as we expect them to be?
We might also miss completeness because modern tools are good at making partial data feel official. Dashboards render something for every period. Warehouses return rows. BI tools happily average over holes. None of that proves the observed reality is whole enough to support a decision.
What completeness breaks in business terms
Completeness failures do not just break dashboards. They break prioritization.
Teams pause healthy campaigns. Product teams investigate imaginary conversion problems. Leaders allocate headcount to the wrong bottleneck. Finance and marketing end up arguing about outcomes when the real disagreement is about what was never captured.
The business cost is not "bad data quality." The business cost is wasted attention.
Once that happens, every smart conversation built on top of the missing data becomes an expensive form of theater.
Collected events are not enough. Data can be present and still be unusable. The next problem is validity: whether the values you captured actually follow the rules that make them meaningful.
You can practice analytics here:
Look, I built this, so it means a lot to me - but this is the only place I know of that you can practice real analytical work - not only queries or scripts and no fake gamifications to get you to do another streak.
Our challenges can take time, and they won't be easy sometimes - but they are all based on the aggregate experience of myself and others and the mistakes we made along the way: